

 Get started
 How-to guides
 Reference
 Concepts
 Self-host gallery
 Appendix

What this covers
The platform is single-node-first. The dashboard node picker only renders once a node besides the local one exists. A
node_id of the empty string is a real, permanent value meaning “the local node”. Auto-placement only picks a remote node when one is registered, schedulable and online.Enrolling a second node
Enrollment exchanges a one-time join token for a client certificate. The agent dials out to the control plane, and the control plane never initiates a connection. For a cloud server created for you, see Node provisioning. To have the control plane set up a machine over SSH, see Enrolling over SSH.1
Mint a join token
- Dashboard
- CLI
- API
Open the Nodes page and click Add node. The dialog shows the
docker and binary commands with copy buttons, plus the expiry time.APP_NODE_JOIN_TOKEN_TTL, clamped to 1 minute through 24 hours). If it expires unused, mint a new one. Tokens cannot be renewed.The request body is optional:When the server knows or was given the control plane address, the response carries
join_commands with a ready-made docker command and binary command.2
Run the agent on the new machine
- Docker
- Binary or package
The agent image runs as root on purpose: it drives Add
/var/run/docker.sock (root-equivalent on the host anyway) and creates a WireGuard device for the mesh.--user 0:0 for images older than v0.2.0-beta.16, which defaulted to a non-root user that could not write into a root-owned directory.On first run the agent generates its own private key, sends only a certificate signing request with the join token, and saves the signed certificate, its key and the control plane’s CA certificate locally. The private key never leaves the machine. On later runs it skips enrollment and reconnects with the saved certificate, which it renews on its own (see Agent certificates).The agent checks that the identity directory is writable before it sends the token. If it is not, it exits naming the directory and says the token was not used, so you can fix permissions and retry with the same token.
3
Confirm it registered
status: pending until its first heartbeat, then online.4
Use it for placement
Once connected, the node is a normal placement target. Pick it in an app or database create form, move an existing resource onto it, or let auto-placement send new resources there.A node accepts app workloads by default but not build workloads. See Build node routing to enable builds.
Node stuck in pending (never connected)
Node stuck in pending (never connected)
A node
pending for more than five minutes (APP_NODE_PENDING_STALE_AFTER) is flagged “Never connected” in the dashboard, and nodes list prints pending (never connected) with the next step. The token was spent but the agent never opened a session, so it cannot be retried.- Check the agent logs on the host. The usual causes are an unwritable identity directory or a wrong
APP_AGENT_ADVERTISE_HOST. - Delete the node with
levelrail-cli nodes delete <id>. - Enroll again with a new token.
Enrolling over SSH instead of by hand
Steps 1 and 2 above can be automated: the control plane SSHes into the machine, mints the token and installs the agent for you.- Dashboard
- CLI
- API
Nodes page, Add node, then Connect over SSH. After the host and port, the Verify server step shows the server’s host key fingerprints. Confirm one before the credential fields appear. The wizard shows each stage plus a live log tail.
- Verifies the host key against the pinned fingerprint, connects, and detects the OS, architecture, and whether Docker and systemd are present. Only Linux with systemd is supported (the same requirement
install.shhas). An unsupported host fails here with a clear reason before anything is changed. - Installs Docker via
get.docker.comif it is missing. - Writes the agent’s environment file and a systemd unit, then enables and starts it (the same steps cloud-init runs on a new VM, see Node provisioning).
- Confirms the service stays active, surfacing the last
journalctllines as the failure reason if it does not.
0600) environment file on the target host. Tokens minted for SSH enrollment are valid for 30 minutes, and for cloud provisioning 60 minutes, regardless of APP_NODE_JOIN_TOKEN_TTL.
Host key verification
Credentials only go to a server whose host key the operator has seen (trust on first use with explicit confirmation).1
Read the host keys
POST /api/v1/nodes/ssh-provision/preflight with {"host": "...", "port": 22} reads the server’s host keys without authenticating: the handshake is aborted right after key exchange, so no username, password or key is sent. It returns each key’s type and SHA256 fingerprint, the same format ssh-keygen -l prints:2
Compare with the server
3
Send the confirmed value back
Pass it as
host_key_fingerprint on POST /api/v1/nodes/ssh-provision. The install refuses to authenticate to a server presenting any other key, and the failure names both the expected and observed fingerprints. A fingerprint you already know (pinned out of band) works without calling the preflight.400 when it carries neither a fingerprint nor insecure_skip_host_key_check: true. That explicit opt out accepts any key, returns a warning in warnings, and writes a node_ssh_provision.host_key_skipped audit entry. The pinned fingerprint is stored with the provision (host_key_fingerprint, host_key_verified). Both routes need the root ability and are audited.
Node health and heartbeat
GET /api/v1/nodes/{id}/health: it returns the stored Heartbeat condition and re-checks any node-scoped alerts (patch status, disk space, resource usage). A node that enrolled but never connected shows NeverConnected, not an error.
How heartbeats work
A connected agent sends aHeartbeat frame up its Session stream at a regular interval (default 15 seconds, APP_NODE_HEARTBEAT_INTERVAL, read agent-side). The control plane only touches last_seen_at when one arrives, never merely because the stream is still open.
The keepalive is configured with
APP_NODE_KEEPALIVE_TIME and APP_NODE_KEEPALIVE_TIMEOUT (default 10s/10s on the control plane; the agent mirrors this with env vars of the same name).
The control plane’s local node
On the Network page the control plane’s own server is always the first card, This server (control plane), whether or not the mesh is on. Apps and databases with an empty placement, or placed on the control plane’s own node ID, belong to it. The Unplaced card only appears for resources placed on a node ID the control plane does not know. The local node uses the same health system: it heartbeats itself rather than through gRPC, and is never permanentlyonline by fiat.
Cordon is tracked as a separate
schedulable flag, not a status value. A node can be online and cordoned, or offline and schedulable.Connection history
Every node status change (online, offline, cordoned) is recorded, the newest 200 per node. See it on the node detail page’s “Connection history” card, or from the CLI:GET /api/v1/nodes/{id}/events?limit=N returns the same list, newest first.
Cordon, drain, uncordon
Cordon marks a node unschedulable for new placements without moving anything already running. Drain moves everything off the node, using the same verified moves described below.Cordon / uncordon
POST /api/v1/nodes/{id}/cordon and .../uncordon are idempotent. A cordoned node is excluded from auto-placement and refused as an explicit placement target (400).
Drain
POST /api/v1/nodes/{id}/drain?target_node_id= starts a drain job and returns 202 with a NodeDrain. The node is cordoned immediately, and a second drain on a node that is already draining returns 409.
Progress is a job: poll
GET /api/v1/node-drains/{id}, or use nodes drain <id> --wait. nodes drains <id> and GET /api/v1/nodes/{id}/drains list the newest 20.
A NodeDrain carries status (running, succeeded, failed), an error, the blocked list and the moves in the order they ran. The node page’s Drain dialog polls it every couple of seconds and lists each move with its phase; the Drains card keeps the history.
Deleting a node
DELETE /api/v1/nodes/{id} (CLI: nodes delete <id>)
- Refused with
409while the node still has anything placed on it. Drain first. - Otherwise idempotent: deleting an already-deleted node ID succeeds.
- Closes the node’s live agent session, so a deleted node’s agent is disconnected.
Simple spread placement (auto-placement)
When you create an app or database without specifying a node, the server decides placement.APP_AUTO_PLACEMENT(default enabled): iffalse, always place on the local node.- If enabled,
autoPlaceNodepicks the schedulable, online node with the fewest resources (apps plus databases). Ties go to the lexicographically smallest node ID. - With no eligible remote node, it falls back to the local node.
- An explicit
node_id(or an explicit empty string meaning “local, on purpose”) always overrides auto-placement and is validated against cordoned and unknown-node checks. - Create responses carry
auto_placed: truewith thenode_idpicked, and the dashboard shows a toast, so it is never a silent decision.
resources.gpu is only auto-placed on a node with a working nvidia runtime and enough free GPUs (least loaded among those), falling back to the local host if it fits. If none fits, the create is refused with 409 and the reason per node; pass node_id to override. See GPU scheduling.
Verified moves
A move relocates one app or database to another node, checking each step and rolling back when the target cannot run it.- CLI
- Dashboard
- API
--to to let the scheduler pick the least loaded eligible node.400 (same node, label mismatch, cordoned or offline target, no eligible node), 404, 409 (that resource is already moving) and 501 (not configured).
Phases
A move walkspreflight, stop_source, copy_volumes, place, verify, stop_old, finalize, then done. If something fails after the source was touched it enters rollback. The final status is succeeded, failed or rolled_back, and every step records its outcome (ok, retry, waiting or failed).
- Stateless (no volumes): stage, verify, switch, stop. The new copy is started and checked on the target before the old one is stopped, so there should be no downtime.
- Stateful (volumes, and every database): stop, copy, start. Downtime lasts until the copy finishes.
Tuning and guarantees
- Moves resume after a control plane restart, and there is one move per resource at a time.
- Apps with host bind mounts are refused, because only Docker named volumes can be copied.
- A database moves with its data volume (and its WAL archive when point-in-time recovery is on). Apps that depend on it are restarted afterwards.
Labels and placement selectors
Label nodes, then restrict where an app or database may run with a selector.GETandPUT /api/v1/nodes/{id}/labelsread and replace a node’s whole label set. Keys are lowercase letters, digits,.,_,-and/, 1 to 63 characters. Values are letters, digits,.,_and-, 1 to 63 characters. At most 32 labels. Invalid input returns400with the reason.GETandPUT /api/v1/apps/{name}/placement(and the same fordatabases) read and set anode_selector. The response listseligible_node_idsand therejectednodes with a reason each. Setting a selector never moves anything by itself.- The dashboard has a Labels card on the node page and a Placement card on the app and database pages.
The spread scheduler
When a move or a drain has no explicit target, the scheduler picks the least loaded eligible node, breaking ties by node id. A node is not eligible when it is cordoned, offline, or missing a label the selector requires.Moving an app with its volumes
- Simple move
- Move with volumes
PUT /apps/{name}/node (CLI: levelrail-cli apps set-node <name> <node-id>) changes only node_id. The reconciler creates fresh empty volumes on the new node and the old volumes stay behind. Fine for stateless apps, wrong for apps with state.Steps
- Stop: the app is suspended and its containers torn down on the current node (synchronously), so nothing writes to volumes during archival.
- Move each volume: every named volume is tarred from the source node and untarred on the destination, one at a time, over the same transport volume backups use. No S3 bucket is needed, because both nodes’ Docker daemons are directly reachable from the control plane.
- Update placement: only after all volumes copy successfully does
node_idchange. - Resume: the suspension clears and the reconciler starts the app on the new node with the already-populated volumes.
Tracking progress
Every step is recorded on astore.AppVolumeMove row. Poll with GET /apps/{name}/moves/{id} or check history with GET /apps/{name}/moves. If step 2 fails on the second of three volumes, the row shows:
stop_app: succeededmove_volume:app-<name>-cache: succeededmove_volume:app-<name>-uploads: failed- (nothing past that)
Special cases
Special cases
- No named volumes, or already on the destination node: takes the simple move path. The response comes back
status: "succeeded", no polling needed. - Bind mounts (
app.yamlhost-path mounts): never moved by this path. Archive and restore primitives exist only for Docker-managed named volumes.
Viewing what’s placed on a node
There is no dedicated “workloads on this node” list. These show it indirectly:- Network page and
levelrail-cli nodes topology: every node with the apps and databases placed on it. See Network topology. - App and database detail pages: a Placement card shows the current node, the selector, eligible nodes and the move action.
- Placement names: an app or database with no explicit node shows “This server” plus the hostname rather than a blank. API responses carry
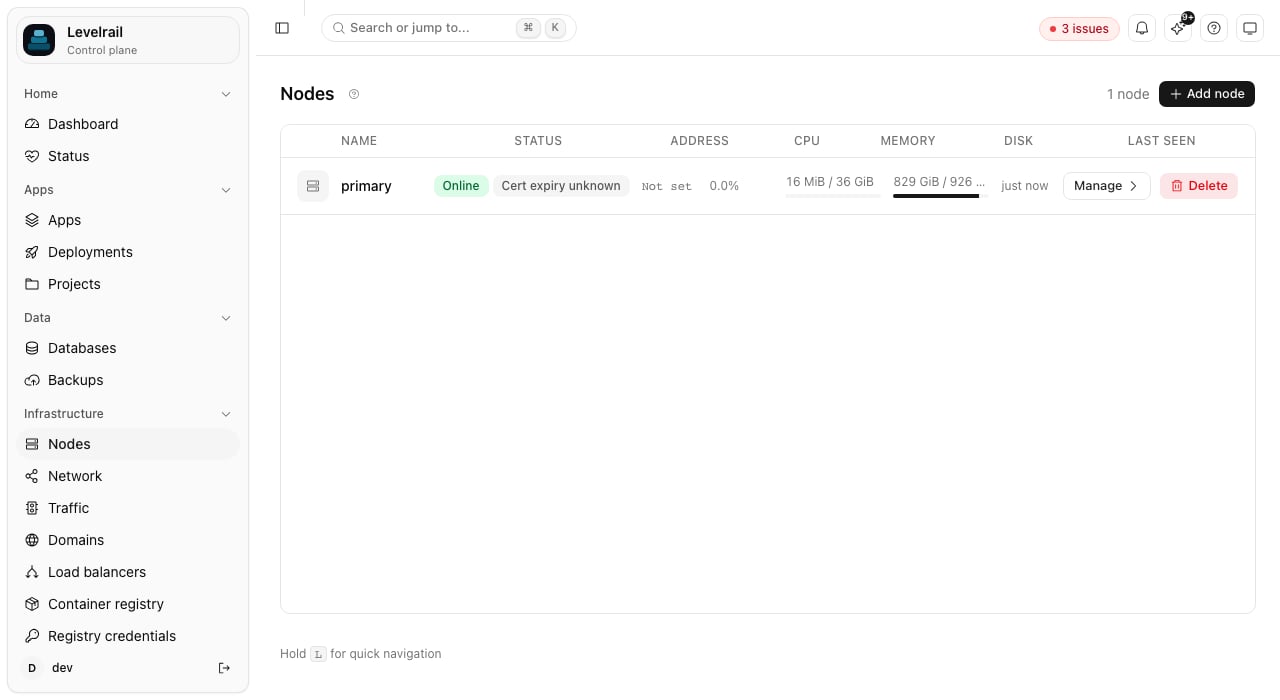
node_nameandnode_is_localbesidenode_id. “Unassigned” appears only when the stored node no longer exists, with a “Move to this server” action. - Nodes page: one row per node with status, usage bars, resource count, agent version and last seen, and a menu for cordon, drain and delete (delete asks you to type the node name).
- Drain and delete: both enumerate everything on the node server-side, which is why deleting a node with placements fails instead of orphaning them.
WireGuard mesh and internal DNS
An app’s database connection string is baked into the container environment at creation time, so it does not rewrite itself when a database moves. The fix is DNS names from the start.internal/reconcile/mesh keeps the mapping current: every pass it reads node and placement data, distributes WireGuard configuration, and rebuilds the internal DNS zone (<brand-short-name>.internal, for example levelrail.internal).
When mesh is enabled, database env vars (like DATABASE_URL, or any { from: postgres.main.url } reference in app.yaml) automatically resolve to the database’s mesh DNS name, so an app on one node can connect to a database on another with no app-side changes. Without mesh, they resolve to the database container’s Docker name, reachable only within that node’s Docker network.
Enabling the mesh on the control plane
Turn it on from Network > Mesh networking in the dashboard, or with the CLI (default: off):/dev/net/tun), that the UDP port is free, whether ufw is blocking it, and whether a public address is set for agents to dial. A failing check blocks enabling and shows a fix hint. The choice is saved and applies on the next control plane restart. Setting APP_MESH_ENABLED on the server pins the mesh on or off and wins over the saved choice (the card then shows it as read-only). A mesh setup failure is logged and the control plane still starts.
Enabling brings up the control plane’s own WireGuard device, interface and mesh address, its own DNS server, and a self-peer entry for the local node.
Single-node DNS caveat: containers do not query port 5390
Single-node DNS caveat: containers do not query port 5390
Docker container DNS accepts only a bare IP address, never a custom port. With the default
:5390, no container actually queries the mesh DNS server and containers fall back to Docker’s embedded resolver. To make containers use it:- Set
APP_MESH_DNS_ADDR=:53. - Grant the process permission to bind port 53 (for example via
setcapon Linux). - Restart the control plane.
Multi-node mesh requirements
The control plane sendsApplyMesh and RotateMeshKey requests to each enrolled agent, and the agent applies them to its own WireGuard device when started with APP_MESH_ENABLED=1. This has been exercised against fakes and a single host with a real TUN device, not between two real hosts, so treat cross-host mesh as lightly proven.
1
Give every agent the privileges
Run as root with
--cap-add NET_ADMIN --device /dev/net/tun -e APP_MESH_ENABLED=1 (the image already runs as root). Nothing else is needed: no extra sysctls and no ip binary. Without these the agent keeps serving containers and logs mesh networking disabled on this node. Nodes enrolled through the dashboard’s SSH or cloud provisioning flows get all of this automatically when the control plane itself runs with APP_MESH_ENABLED=1.2
Open the hub
The control plane is the hub: agents send WireGuard handshakes to
APP_AGENT_ADVERTISE_HOST on UDP 51820. Set that variable to the control plane’s public host, and allow inbound UDP 51820 on its firewall and cloud security group. A loopback advertise host leaves agents with no endpoint (no known endpoint for peer); levelrail-cli doctor reports this as mesh_hub_endpoint.3
Match the brand
The interface name comes from the brand short name. The agent image carries the default
brand.yaml; override with APP_BRAND_SHORT_NAME (or mount your own at APP_BRAND_FILE) if you rebrand the control plane.51820, so workers reach each other directly without extra configuration.
Viewing mesh status
- CLI
- API
A peer with
live: false is registered in the node inventory but the mesh device has no live entry yet (the reconciler has not reached it this pass, or peering has not converged).
Pair diagnostics
GET /api/v1/mesh/connectivity returns every node’s WireGuard view of every other node as pairs, each ok, degraded, down or unknown, with a per-direction link state (healthy, stale, never, no_peer, unknown), last handshake, endpoint and a hint for a bad pair. It returns 501 when the mesh is off. The Network page shows the same matrix under Node connectivity.
Rotating a node’s mesh key
Generates a fresh WireGuard keypair for a node and makes it that node’s live mesh identity immediately. Works for any node with a live session, local or remote.- CLI
- API
- The new public key is recorded and the mesh reconciler propagates it to every peer on its next pass.
- Watch the
rotationfield inlevelrail-cli nodes meshto see when every reachable peer has caught up. A brief reconnect blip on mesh traffic is possible until then. - A remote node with no live agent session fails the rotation. Both routes return
501when mesh networking is not enabled.
levelrail-cli nodes rejoin-mesh <node-id> (POST /api/v1/nodes/{id}/mesh/rejoin) forces an immediate mesh reconcile. It is a fleet-wide resync, not a per-node operation.
Cross-node database connections
With the mesh on, an app on one node can use a database on another.- The app’s
DATABASE_URLuses<db>.<zone>:<mesh port>. - The name is pinned in the container’s
/etc/hoststo the database node’s mesh address, so no DNS server has to be reachable from the container. - Mesh ports are allocated from
APP_MESH_DB_PORT_MINtoAPP_MESH_DB_PORT_MAX(default21000to21999). - A database is published on its node’s mesh address only once an app on another node uses it, and never on a wildcard or public address.
- Without the mesh, a move that would split an app from its database is refused, except inside a drain.
Routing to apps on remote nodes
The embedded Caddy ingress (Domains and ingress) runs in the control plane’s own process. A worker node has no public listener: nothing is bound to 80/443 there. Ingress reaches an app on a worker through that node’s mesh address, so its domains and its
<app>.<ip>.sslip.io hostname work with normal TLS.- The app controller publishes the container’s main port on the worker’s mesh address (for example
10.181.0.2:32768), never on0.0.0.0and never on a public interface. - The ingress controller dials
<mesh-ip>:<host-port>and obtains the TLS certificate for the hostname as usual (ACME for custom domains and sslip.io names, or your uploaded certificate). - The path counts as healthy when the node has a mesh address and the control plane’s WireGuard device has a handshake with it from the last 3 minutes.
bind_address and host_port:
Only the app’s main port moves. App streams, managed databases and every unpublished container port are untouched: a database is never bound to the mesh address by this feature.
The mesh came up after the app was deployed
The mesh came up after the app was deployed
The reconciler is level-triggered: when it sees a running container whose main port is still on loopback and the path is now healthy, it removes that container and recreates it with the mesh bind (a brief restart; the app was unreachable through ingress anyway). A mesh flap never recreates a container: once bound, it stays bound while the path is down, and the condition reports the outage.This does not move databases or app streams onto the mesh, and auto-placement still prefers the control plane’s own node for apps created with a domain.
Agent certificates: renewal and re-enrollment
Each agent authenticates with a client certificate issued by the control plane’s own CA (90 days by default,APP_AGENT_CERT_VALIDITY on the control plane). The design and its rejected alternatives are in ADR 021.
Seeing expiry
Healthy agents renew with about 30 days left, so either alert firing means renewal is failing. Existing nodes get an estimated expiry (enrollment time plus 90 days) until they next connect.
Automatic renewal
When a certificate is two thirds of the way through its lifetime (APP_AGENT_CERT_RENEW_FRACTION on the agent, default 0.67, plus random jitter so nodes enrolled together do not renew together), the agent generates a fresh key and asks the control plane to sign it over its existing authenticated connection. Nothing needs restarting.
- The control plane signs the request and records the new certificate. The previous one stays accepted for a grace window (
APP_AGENT_CERT_RENEW_GRACE, default24h), so a lost response or a control plane restart never locks the node out. - The agent writes the new identity next to the old one (temp file, fsync, rename, the old one kept as
<identity file>.prev) and tests it with a separate connection. - If the test passes the agent switches over and drops the backup. If it fails it restores the old identity and retries with backoff (1 minute doubling to 1 hour).
Nodes enrolled before agents generated their own keys keep working, and their first renewal moves them to an agent-generated key. Older agents still enroll against a newer control plane and get a server-generated key. The control plane now refuses that by default. Set
APP_AGENT_REQUIRE_CSR=false on the control plane to accept legacy agents until they are upgraded.Re-enrolling a node
A node that was offline past its certificate’s expiry, or whose certificate was revoked, cannot renew. Re-enroll it instead; it keeps its node ID, placements and history.1
Mint a re-enroll token
Dashboard: open the node and click Re-enroll node. CLI:
levelrail-cli nodes reenroll-token <id>. Both mint a single-use token bound to that node, valid for 15 minutes, and show the command once.2
Run the command on the node
Revoking a certificate
Revoke certificate on the node page,levelrail-cli nodes revoke-cert <id>, or POST /api/v1/nodes/{id}/revoke-cert makes the control plane refuse the node’s certificate and closes its live session immediately.
Agent version
Every agent reports its version, commit, OS and architecture when its session opens. SetAPP_AGENT_MIN_VERSION on the control plane (for example v0.9.0) to flag older agents, and agents too old to report a version, as outdated in the node list, node page, CLI and attention list. Unset, no agent is flagged. Upgrading agents is still manual: stop the agent, replace the binary, start it again.
Node-level metrics
GET /api/v1/nodes/{id}/metrics returns summed container metrics, not host metrics, except for disk.
memory_limit_bytesis excluded because summing unconstrained container limits would multiply the host’s memory by N.- The dashboard labels summed metrics with “summed across N containers”.
resource_countis how many placed services contributed a sample in the queried range, a rough occupancy signal.- Databases placed on a node are excluded from the sum (only app services are included). Including them is separate future work.
Fleet-wide utilization
GET /api/v1/nodes/resource-usage is the fleet-wide counterpart: one snapshot with every node’s latest CPU, memory and disk reading plus a rollup, read by the node list’s CPU/Memory/Disk columns and the dashboard’s fleet summary card. The same caveats apply: CPU and memory are summed from containers, and disk is a real host reading that today is populated only for the node running the control plane. See Observability for the response shape.
OS patch status
GET /api/v1/nodes/{id}/patch-status reads the latest OS patch sample. Collection runs every APP_OS_PATCH_CHECK_INTERVAL (default 1 hour), with a lookback of up to 48 hours to cover slow or just-restarted collectors.
The dashboard renders this as a single status badge, not a chart, since it is one current fact.
API reference
Node routes require theroot ability, not read or write, because node management is control-plane administration.
GET /api/v1/nodes/{id} also carries an alert_status field when telemetry is configured, a live re-evaluation of that node’s patch status, disk space and resource usage alerts. PUT /api/v1/apps/{name}/node and move-with-volumes are root too, because move-with-volumes changes placement and does a full-overwrite restore of every named volume.
CLI
nodes workloads is a full replace of both flags, not a per-field patch. Both --accepts-app and --accepts-build are required on every call, so one flag can never silently reset to false. See Build node routing for what accepts_build_workloads does.Not built yet
Resource-aware scheduling
Resource-aware scheduling
The spread scheduler counts placements and filters on cordon, status and labels, never CPU, memory or disk headroom. Resource-aware scheduling is not built. Bin-packing and affinity rules are a deliberate non-goal.
Agent self-update
Agent self-update
Upgrading an agent is still manual: stop it, replace the binary or image, start it again. The control plane only flags outdated agents.
Node-specific change history
Node-specific change history
Cordon, drain and workload changes appear in the platform audit log (
GET /api/v1/audit-log). Only connection events (online, offline, cordoned) have a per-node history view.Related pages
Node provisioning
Create nodes at a cloud provider.
Build node routing
Choose which node runs builds.
Network topology
See every node with its apps, databases and connections.
Domains and ingress
How the control plane’s ingress routes to apps.
Backups and storage
Move app volumes to another node.
Observability
Per-node metrics, resource usage and patch status.